Capture with Retina CLI
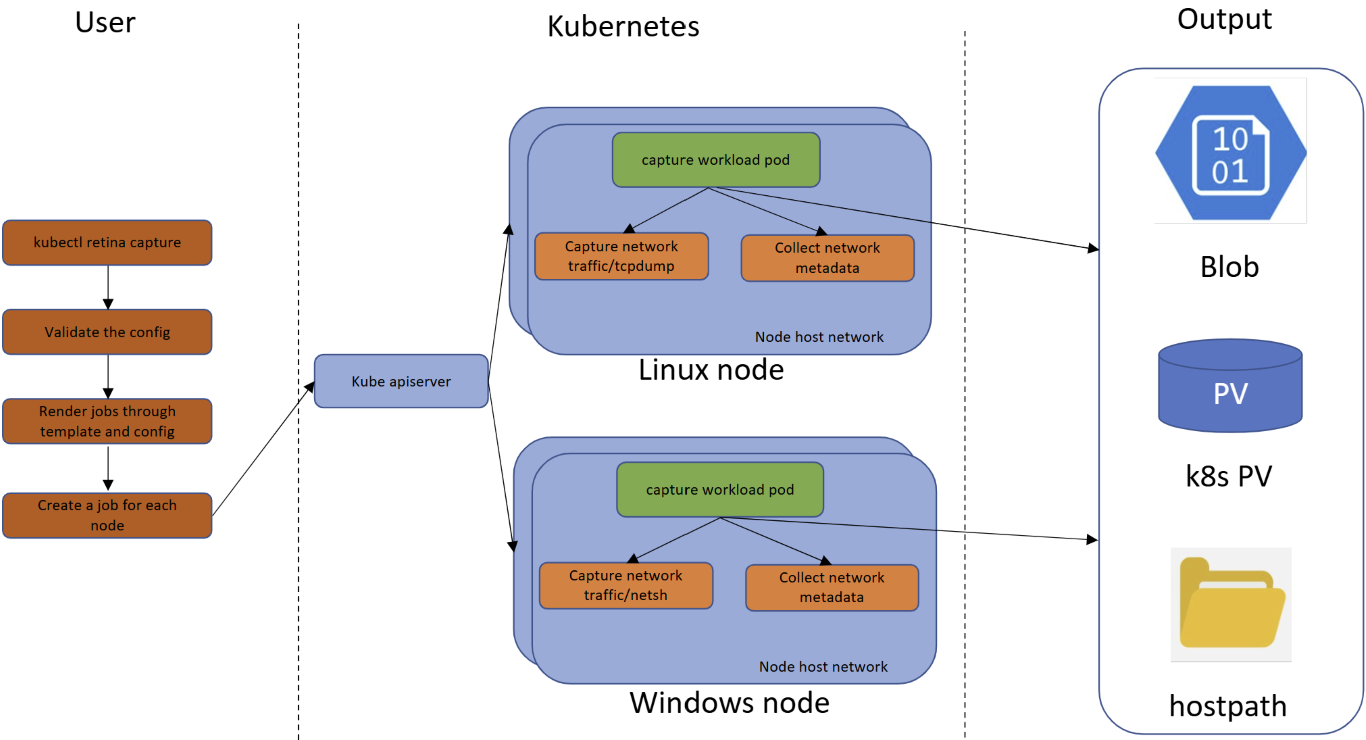
This page describes how the Retina CLI works in the context of performing packet captures.
The use of the Retina CLI to perform captures does NOT require the Retina operator pod to be running.
See the overview for a description of how the capture jobs are created.
Prerequisites
- Install Retina CLI
- Sufficient node storage for capture files when using the default
--host-pathoutput, unless a remote output location (blob, S3, or PVC) is configured instead.
Cluster Access
The identity running kubectl retina capture commands needs Kubernetes RBAC permissions in the target cluster:
| Resource | Verbs | Scope | Notes |
|---|---|---|---|
nodes | get, list | cluster | Resolve --node-selectors/--node-names |
namespaces | get, list | cluster | Resolve --namespace-selectors; the target namespace must already exist |
pods | get, list | cluster | Resolve --pod-selectors/--pod-names and track capture job pods |
jobs (batch/v1) | create, get, list, delete | namespace | Create/monitor/clean up the per-node capture Jobs |
secrets | create, get, update, delete | namespace | Stores the Blob SAS token or S3 credentials mounted into capture pods |
persistentvolumeclaims | get | namespace | Only required when using --pvc (the PVC must already exist) |
pods | create, delete | namespace | Only required for kubectl retina capture download, which creates a temporary pod to read files off the node |
pods/exec | create | namespace | Only required for kubectl retina capture download, to stream file contents out of the temporary pod |
Cluster Admission Policies
Capture Jobs run their Pods with elevated settings in order to capture host traffic. If the cluster enforces restrictive admission policies (e.g. Azure Policy, Gatekeeper, Kyverno), the capture namespace/workload must be allowed to use:
- Host network (
hostNetwork: true) - required so the capture pod can see the node's network interfaces. - Host IPC (
hostIPC: true) - required by the underlying capture tooling. NET_ADMINandSYS_ADMINLinux capabilities - required to run the packet capture on the host's interfaces.- The capture image's registry - the default capture image is pulled from
ghcr.io/microsoft/retina/retina-agent. If the cluster restricts pulls to an approved registry, either allow-list this image/registry, or mirror the image into your approved registry and override it viaRETINA_AGENT_IMAGE(see Debug mode).
If your cluster denies any of these, the capture Job's pod will fail admission and the capture will not run.
To surface asynchronous Pod admission failures when using capture create --no-wait=true, the caller must be able to list Events and list Jobs in the capture namespace. Check access with:
kubectl auth can-i list events --namespace <capture-namespace>
kubectl auth can-i list jobs.batch --namespace <capture-namespace>
With these permissions, the CLI checks Job startup for up to five seconds. It returns a detected FailedCreate error only if the Job has not started by the end of that window. A successful command remains best-effort and does not guarantee that every capture Pod has started. If Event access is unavailable, capture creation remains backward compatible and returns after creating the Jobs with a warning that startup could not be checked.
Operations
Capture Create
kubectl retina capture create [--flags] creates a Capture with underlying Kubernetes jobs.
Selecting a Target
The target indicates where the packet capture will be performed. This can be set via the following flags:
--node-selectors(label-based node selection)--node-names(specific nodes, matched by hostname)--pod-names(specific pods in the namespace set by--namespace)--pod-selectorsand--namespace-selectors(label-based pod selection)
Exactly one of the following target types can be used per capture:
| Target type | Flags | Notes |
|---|---|---|
| Nodes | --node-selectors and/or --node-names | When both are set, a node must match both. |
| Pods by label | --pod-selectors, optionally with --namespace-selectors | --namespace-selectors alone is not a valid target. Without it, pods are looked up in the namespace set by --namespace. |
| Pods by name | --pod-names | Pods are looked up in the namespace set by --namespace. |
The following combinations are not allowed and fail with an error:
- Node targets (
--node-selectors,--node-names) cannot be combined with--pod-selectors,--namespace-selectors, or--pod-names. Note that--node-namesis a node target, so it conflicts with the pod flags as well. --pod-namescannot be combined with--pod-selectorsor--namespace-selectors.--namespace-selectorsrequires--pod-selectors.
If nothing is set, kubectl retina capture create will use --node-selectors with the default value shown below in Flags. The default --node-selectors value is dropped automatically when any of --node-names, --pod-selectors, --namespace-selectors, or --pod-names is set (this also applies if you explicitly pass the default value kubernetes.io/os=linux). Passing any other --node-selectors value together with those flags is an error.
You can find target selection examples below.
Configuring the Output Location
The output configuration indicates the location where the capture will be stored. At least one location needs to be specified. This can either be the host path on the node, or a remote storage option. --host-path has a default value, so captures are stored on the node unless it is explicitly set to an empty string.
--host-path is a relative subpath name (for example my-captures) that is created under the node directory set by --host-path-base-dir (default /var/log/retina/captures). Absolute paths, .. segments, and characters that are not valid in a path segment are rejected. With the defaults, files are stored in /var/log/retina/captures/retina on the node.
Blob-upload requires a Blob Shared Access Signature (SAS) with the write permission to the storage account container, to create SAS tokens in the Azure portal, please read: Create SAS Tokens in the Azure Portal.
You can find output configuration examples below.
Stopping a Capture
The Capture can be stopped in a number of ways:
- In a given time, by the
durationflag, or when the file reaches the maximum allowed file size defined by themax-sizeflag.- When both are specified, the capture will stop whenever either condition is first met.
- On demand by deleting the capture before the specified conditions meets.
When using --file-count (rotating capture mode), --max-size does not stop the capture. Instead, the capture rotates through a fixed number of files of that size. Because --duration defaults to 1m0s, set --duration 0 for the capture to keep running until you delete it, otherwise it stops once the duration expires. See Rotating Capture (Long-Running) for examples and how to retrieve the files.
The network traffic will be uploaded to the specified output location.
Flags
| Flag | Type | Default | Description | Notes |
|---|---|---|---|---|
blob-upload | string | "" | Blob SAS URL with write permission to upload capture files. | |
cleanup-after-upload | bool | false | Automatically clean up capture files from the node's host path after successful upload to remote storage (blob, S3, or PVC). Requires a remote storage destination (--blob-upload, --s3-bucket, or --pvc). | |
debug | bool | false | When debug is true, a customized retina-agent image, determined by the environment variable RETINA_AGENT_IMAGE, is set. | |
duration | string | 1m0s | Maximum duration of the packet capture - in minutes / seconds. | |
exclude-filter | string | "" | A comma-separated list of IP:Port pairs that are excluded from capturing network packets. Supported formats are IP:Port, IP, Port, :Port, IP: | Only works on Linux. |
file-count | int | 0 | Number of capture files in a rotating buffer. When set (minimum 1), creates a rolling capture where the oldest file is overwritten once the limit is reached. Requires --max-size to define per-file size. Useful for long-running captures of intermittent issues. | Only works on Linux. |
help | Help for create command. | |||
host-path | string | retina | Subpath name under --host-path-base-dir in which the capture files are stored on the node. | Must be a relative subpath; absolute paths and .. are rejected. |
host-path-base-dir | string | /var/log/retina/captures | Absolute base directory on the node under which --host-path is joined. | The CLI creates the capture jobs with your own credentials, so you choose the base directory. When using the operator, the base directory is set by the cluster administrator with the Helm value capture.hostPathBaseDir and cannot be changed by the Capture author. |
include-filter | string | "" | A comma-separated list of IP:Port pairs that are included from capturing network packets. Supported formats are IP:Port, IP, Port, :Port, IP: | Only works on Linux. |
include-metadata | bool | true | Collect static network metadata into the capture file if true. | |
job-num-limit | int | 0 | The maximum number of jobs which can be created for each capture. The default value 0 indicates no limit. This can be configured by CLI flags for each CLI command, or by a config map consumed by the retina-operator. When creating a job requires job number exceeds this limit, it will fail with prompt like Error: the number of capture jobs 3 exceeds the limit 2. | |
max-size | int | 100 | Maximum size of the capture file in MB. When used with --file-count, this becomes the per-file size limit for rotating captures. | Only works on Linux. |
name | string | retina-capture | A name for the Retina Capture. | |
namespace | string | default | Sets the namespace which hosts the capture job and the other Kubernetes resources for a network capture. | Ensure the namespace exists. |
namespace-selectors | string | "" | Capture network captures on pods filtered by the provided namespace selectors. | Requires pod-selectors; not compatible with node-selectors, node-names, or pod-names. |
node-names | string | "" | A comma-separated list of node names to select nodes on which the network capture will be performed. | Overrides the default node-selectors value, allowing captures on nodes of any OS (including Windows). Not compatible with pod-selectors, namespace-selectors, or pod-names. |
node-selectors | string | kubernetes.io/os=linux | A comma-separated list of node labels to select nodes on which the network capture will be performed. | The default value is cleared automatically when node-names, pod-selectors, pod-names, or namespace-selectors are specified. A non-default value is not compatible with pod-selectors, namespace-selectors, or pod-names. |
no-wait | bool | true | By default, Retina capture CLI will exit before the jobs are completed. If false, the CLI will wait until the jobs are completed and clean up the Kubernetes resources created. | |
packet-size | int | 0 | Limit the packet size in bytes. Packets longer than the defined maximum size will be truncated. The default value 0 indicates no limit. This is beneficial when the user wants to reduce the capture file size or hide customer data due to security concerns. | Only works on Linux. |
pod-names | string | "" | A comma-separated list of specific pod names to select pods on which the network capture will be performed. | Mutually exclusive with node-selectors, node-names, pod-selectors, and namespace-selectors. Pods are looked up in the namespace set by --namespace. |
pod-selectors | string | "" | A comma-separated list of pod labels to select pods on which the network capture will be performed. | Can be paired with namespace-selectors to match pods across namespaces. If namespace-selectors is omitted, matching pods are looked up in the namespace set by --namespace only. |
pvc | string | "" | PersistentVolumeClaim under the specified or default namespace to store capture files. | |
s3-access-key-id | string | "" | S3 access key id to upload capture files. | |
s3-bucket | string | "" | Bucket in which to store capture files. | |
s3-endpoint | string | "" | Endpoint for an S3 compatible storage service. Use this if you are using a custom or private S3 service that requires a specific endpoint. | |
s3-path | string | retina/captures | Prefix path within the S3 bucket where captures will be stored. | |
s3-region | string | "" | Region where the S3 compatible bucket is located. | |
s3-secret-access-key | string | "" | S3 access secret key to upload capture files. | |
source-ips | string | "" | A comma-separated list of source IP addresses to filter captured packets by; a packet is captured if it matches any of these IPs. When combined with --destination-ips, a packet must match at least one source IP and at least one destination IP to be captured. | |
destination-ips | string | "" | A comma-separated list of destination IP addresses to filter captured packets by; a packet is captured if it matches any of these IPs. When combined with --source-ips, a packet must match at least one source IP and at least one destination IP to be captured. | |
interfaces | string | "" | Comma-separated list of network interfaces to capture on (e.g., "eth0,eth1"). By default, captures are performed on all network interfaces. | |
pcap-filter | string | "" | BPF filter expression for packet filtering (e.g., "host 10.0.0.1", "tcp port 443"). See PCAP-FILTER for BPF syntax. Does NOT accept flags (arguments starting with '-'). | |
tcpdump-filter | string | "" | DEPRECATED and will be removed. Use --pcap-filter instead. BPF filter expression for packet filtering. Does NOT accept flags (arguments starting with '-'). | Cannot be combined with --source-ips or --destination-ips. |
no-promiscuous | bool | false | Disable promiscuous mode (equivalent to tcpdump -p flag). | |
packet-buffered | bool | false | Enable packet-buffered output (equivalent to tcpdump -U flag). | |
immediate-mode | bool | false | Enable immediate mode for packet capture (equivalent to tcpdump --immediate-mode). | |
no-resolve-dns | bool | false | Don't resolve hostnames (equivalent to tcpdump -n flag). | |
no-resolve-port | bool | false | Don't resolve hostnames or port names (equivalent to tcpdump -nn flag). | |
verbosity | string | "" | Verbosity level: verbose (tcpdump -v), extra (tcpdump -vv), max (tcpdump -vvv). Mutually exclusive. | |
timestamp-format | string | "" | Timestamp format: none (-t), unformatted (-tt), delta (-ttt), date (-tttt), delta-since-first (-ttttt). Mutually exclusive. | |
print-data | string | "" | Print packet data: hex (-x), hex-with-link (-xx), ascii (-A), ascii-with-link (-AA). Mutually exclusive. | |
print-link-header | bool | false | Print link-level headers (equivalent to tcpdump -e flag). | |
quiet-output | bool | false | Quick/quiet output mode (equivalent to tcpdump -q flag). | |
absolute-seq | bool | false | Print absolute TCP sequence numbers (equivalent to tcpdump -S flag). | |
dont-verify-checksum | bool | false | Don't verify TCP checksums (equivalent to tcpdump -K flag). |
Note on Mutually Exclusive Flags: The
verbosity,timestamp-format, andprint-dataflags are mutually exclusive within their respective groups. You can only set one value per flag. For example, you cannot use both--verbosity=verboseand--verbosity=maxsimultaneously. The CLI enforces this by using enum-based flags instead of individual boolean flags.
Examples
Target Selection
Node Selectors
kubectl retina capture create \
  --name example-node-selectors \
  --node-selectors "kubernetes.io/os=linux"
Node Names
kubectl retina capture create \
  --name example-node-names \
  --node-names "aks-agentpool-26113504-vmss000000,aks-agentpool-26113504-vmss000001"
Pod Selectors & Namespace Selectors (Pairs)
kubectl retina capture create \
  --name example-pod-namespace-selectors \
  --pod-selectors="k8s-app=kube-dns" \
  --namespace-selectors="kubernetes.io/metadata.name=kube-system"
Pod Selectors without Namespace Selectors (scoped to --namespace)
kubectl retina capture create \
  --name example-pod-selectors-own-namespace \
  --namespace myapp \
  --pod-selectors="k8s-app=my-app"
Pod Names (Specific Pods)
kubectl retina capture create \
  --name example-pod-names \
  --namespace myapp \
  --pod-names "my-app-pod-abc123,my-app-pod-def456"
Single Pod by Name
kubectl retina capture create \
  --name example-single-pod \
  --namespace myapp \
  --pod-names "my-app-pod-abc123" \
  --duration 60s
Interface Selection
Capture on all interfaces (default behavior)
kubectl retina capture create \
  --name example-all-interfaces \
  --node-selectors "kubernetes.io/os=linux"
Capture on specific interfaces
kubectl retina capture create \
  --name example-specific-interfaces \
  --node-selectors "kubernetes.io/os=linux" \
  --interfaces "eth0,eth1"
Rotating Capture (Long-Running)
Rotating captures are useful for debugging intermittent issues where you don't know when the problem will occur. The capture runs continuously, keeping only the most recent traffic in a fixed number of files.
Basic rotating capture (10 files × 100MB = 1GB rolling buffer, running until it is deleted):
kubectl retina capture create \
  --name example-rotating \
  --node-selectors "kubernetes.io/os=linux" \
  --max-size 100 \
  --file-count 10 \
  --duration 0 \
  --no-wait \
  --host-path example-rotating
Rotating capture with a time limit (stop after 4 hours):
kubectl retina capture create \
  --name example-rotating-timed \
  --node-selectors "kubernetes.io/os=linux" \
  --max-size 50 \
  --file-count 20 \
  --duration 4h \
  --no-wait \
  --host-path example-rotating-timed
Once the issue is reproduced, stop the capture by deleting it:
kubectl retina capture delete --name example-rotating
Retrieving the files of a rotating capture
The capture files are only written to the output location when the capture stops. While it runs, they exist only inside the capture pod. When the capture is deleted, each capture pod is signaled to stop, archives the rotating buffer (up to file-count × max-size MB) into a <capture-name>-<node-name>-<start-timestamp>.tar.gz tarball, and copies it to the output location. The pod has up to 30 minutes to finish, and the upload can take a while for large buffers.
Deleting the capture also removes its jobs and pods, and kubectl retina capture download --name only works with pods that completed successfully. For a capture that you stop by deleting it, retrieve the tarballs from the output location instead:
-
Remote storage (recommended): Create the capture with
--blob-upload,--s3-bucket, or--pvcand download the tarballs from there once the capture pods are gone. For Azure Blob Storage, you can usekubectl retina capture download --blob-url. With S3, the tarballs are stored under the--s3-pathprefix of the bucket. With a PVC, they are stored in the volume. -
Node host path: If you only used the default
--host-path, the tarballs are on each node that ran a capture pod, in--host-path-base-dir/--host-path(/var/log/retina/captures/example-rotatingin the example above).-
Before deleting the capture, note which nodes run the capture pods:
kubectl get pods --namespace <capture-namespace> --selector capture-name=example-rotating --output wide -
Delete the capture and wait until its pods are gone, which means the tarballs have been written.
-
Start a debug pod on each node. The node's file system is available under
/hostin the debug pod. The command prints the name of the debug pod it creates:kubectl debug node/<node-name> --image=busybox -- sleep 3600 -
Copy the tarball out of the debug pod, then delete the debug pod:
kubectl exec <debug-pod-name> -- ls /host/var/log/retina/captures/example-rotatingkubectl cp <debug-pod-name>:/host/var/log/retina/captures/example-rotating/<tarball-name> ./<tarball-name>kubectl delete pod <debug-pod-name>
If you cannot use
kubectl debug, you can read the same path through SSH or any other node access. -
If you know roughly how long you need to wait for the issue to occur, you can use a long but bounded --duration (as in the second example above) instead of --duration 0. The capture then completes on its own, its pods are kept, and kubectl retina capture download --name can be used to retrieve the files. See Obtaining the output for how to extract and read the tarball.
Output Configuration
Host Path
kubectl retina capture create \
  --name example-host-path \
  --host-path example/captures
PVC
kubectl retina capture create \
  --name example-pvc \
  --pvc mypvc
Storage Account
kubectl retina capture create \
  --name example-blob \
  --blob-upload <Blob SAS URL with write permission>
AWS S3
kubectl retina capture create \
  --name example-s3 \
  --s3-bucket "your-bucket-name" \
  --s3-region "eu-central-1" \
  --s3-access-key-id "your-access-key-id" \
  --s3-secret-access-key "your-secret-access-key"
S3 Compatible Service (MinIO)
kubectl retina capture create \
  --name example-minio \
  --s3-bucket "your-bucket-name" \
  --s3-endpoint "https://play.min.io:9000" \
  --s3-access-key-id "your-access-key-id" \
  --s3-secret-access-key "your-secret-access-key"
Capture Filters
Include / Exclude Filters
kubectl retina capture create \
  --name example-include-exclude-filters \
  --include-filter="10.224.0.42:80,10.224.0.33:8080" \
  --exclude-filter="10.224.0.26:80,10.224.0.34:8080"
BPF Packet Filters
kubectl retina capture create \
  --name example-pcap-filters \
  --pcap-filter="udp port 53"
Source / Destination IP Filters
kubectl retina capture create \
  --name example-source-destination-ip \
  --source-ips="10.224.0.42" \
  --destination-ips="10.224.0.33,10.224.0.34"
This captures only packets whose source IP is 10.224.0.42 and whose destination IP is either 10.224.0.33 or 10.224.0.34. --source-ips and --destination-ips can each be used on their own, and work on both Linux and Windows nodes.
Capture with Display Options
kubectl retina capture create \
  --name example-with-display-options \
  --pcap-filter="tcp port 443" \
  --no-resolve-dns \
  --verbosity=verbose \
  --print-data=hex
This example:
- Captures only HTTPS traffic (tcp port 443)
- Doesn't resolve hostnames (--no-resolve-dns, equivalent to tcpdump -n)
- Shows verbose output (--verbosity=verbose, equivalent to tcpdump -v)
- Displays packet data in hex (--print-data=hex, equivalent to tcpdump -x)
Additional display option examples:
# Don't resolve names or ports, capture HTTP traffic
kubectl retina capture create \
  --name example-http \
  --pcap-filter="tcp port 80" \
  --no-resolve-port

# Show timestamps with date and link-level headers for ICMP
kubectl retina capture create \
  --name example-icmp \
  --pcap-filter="icmp" \
  --timestamp-format=date \
  --print-link-header
Capture Delete
Deleting the capture job before either of the terminating conditions have been met will stop the capture.
kubectl retina capture delete --name <string> deletes a Kubernetes Jobs with the specified Capture name.
Example:
kubectl retina capture delete --name retina-capture
Capture List
To get a list of the captures you can run kubectl retina capture list to get the captures in a specific namespace or in all namespaces.
List by namespace:
kubectl retina capture list --namespace capture
List by all namespaces:
kubectl retina capture list --all-namespaces
-A can be used as a shorthand for --all-namespaces.
Capture Download
The kubectl retina capture download command allows you to download capture files directly from the cluster or from blob storage.
Download from Cluster
Download capture files using the capture name:
kubectl retina capture download --name <capture-name>
Download capture files and specify an output location:
kubectl retina capture download --name <capture-name> -o <output-location>
Download all available captures in the current namespace:
kubectl retina capture download --all
Download all available captures from all namespaces:
kubectl retina capture download --all --all-namespaces
By default, files are downloaded to the current directory.
Download from Blob Storage
Download capture files from Azure Blob Storage using a Blob URL (requires Read/List permissions):
kubectl retina capture download --blob-url "<blob-url>"
Download Output Structure
The command will create different output structures depending on the options used:
Individual Capture Download
For individual capture downloads using --name, files are organized by capture name:
/output-directory/
└── capture-name/
    ├── capture-name-node1-20230320013600UTC.tar.gz
    └── capture-name-node2-20230320013600UTC.tar.gz
All Captures Download
When using --all, all captures are consolidated into a single timestamped archive:
/output-directory/
└── all-captures-20230320134500.tar.gz
The archive contents are organized by capture name:
# Contents of all-captures-20230320134500.tar.gz
capture-name-1/
├── capture-name-1-node1-20230320013600UTC.tar.gz
└── capture-name-1-node2-20230320013600UTC.tar.gz
capture-name-2/
├── capture-name-2-node1-20230320014500UTC.tar.gz
└── capture-name-2-node2-20230320014500UTC.tar.gz
All Captures with All Namespaces
When using --all --all-namespaces, the archive contents include namespace information:
# Contents of all-captures-20230320134500.tar.gz
namespace-1/
└── capture-name-1/
    ├── capture-name-1-node1-20230320013600UTC.tar.gz
    └── capture-name-1-node2-20230320013600UTC.tar.gz
namespace-2/
└── capture-name-2/
    ├── capture-name-2-node1-20230320014500UTC.tar.gz
    └── capture-name-2-node2-20230320014500UTC.tar.gz
Download Options
| Flag | Description | Notes |
|---|---|---|
--name | Download capture files for a specific capture name | Creates individual files in capture-specific directory |
--all | Download all available captures in the current namespace | Creates single consolidated archive |
--all-namespaces | Download captures from all namespaces (requires --all) | Includes namespace in archive structure |
--blob-url | Download from Azure Blob Storage using SAS URL | Requires Read/List permissions |
-o, --output | Specify output directory | Defaults to current directory |
Examples
Download a specific capture:
kubectl retina capture download --name my-capture
Download all captures with custom output location:
kubectl retina capture download --all -o /tmp/retina-downloads
Download all captures from all namespaces:
kubectl retina capture download --all --all-namespaces
Download from blob storage:
kubectl retina capture download --blob-url "https://mystorageaccount.blob.core.windows.net/captures?sp=rl&st=..."
Obtaining the output
After downloading or copying the tarball from the location specified, extract the tarball through the tar command in either Linux shell or Windows Powershell, for example,
tar -xvf retina-capture-aks-nodepool1-41844487-vmss000000-20230320013600UTC.tar.gz
Name pattern of the tarball
The tarballs take the following name pattern, $(capturename)-$(hostname)-$(date +%Y%m%d%H%M%S%Z).tar.gz.
- e.g.
retina-capture-aks-nodepool1-41844487-vmss000000-20230313101436UTC.tar.gz
File and directory structure inside the tarball
- Linux
├── ip-resources.txt
├── iptables-rules.txt
├── retina-capture-aks-nodepool1-41844487-vmss000000-20230320013600UTC.pcap
├── proc-net
│   ├── anycast6
│   ├── arp
... ...
├── proc-sys-net
│   ├── bridge
... ...
|-- socket-stats.txt
`-- tcpdump.log
- Windows
│   retina-capture-akswin000002-20230322010252UTC.etl
│   retina-capture-akswin000002-20230322010252UTC.pcap
│   netsh.log
│
└───metadata
    │   arp.txt
        ... ...
    │
    ├───adapters
    │       6to4 Adapter_int.txt
            ... ...
    │
    ├───logs
    │   ├───cbs
    │   │       CBS.log
    │   │
    │   ├───dism
    │   │       dism.log
    │   │
    │   └───NetSetup
    │           service.0.etl
                ... ...
    │
    ├───wfp
    │       filters.xml
    │       netevents.xml
    │       wfpstate.xml
    │
    └───winevt
            Application.evtx
            ... ...
Network metadata
-
Linux
- IP address configuration (ip -d -j addr show)
- IP neighbor status (ip -d -j neighbor show)
- IPtables rule dumps
- iptables-save
- iptables -vnx -L
- iptables -vnx -L -t nat
- iptables -vnx -L -t mangle
- Network statistics information
- ss -s (summary)
- ss -tapionume (socket information)
- networking stats (/proc/net)
- kernel networking configuration (/proc/sys/net)
-
Windows
- reference: Microsoft SDN Debug tool
Debug mode
With debug mode, when --debug is specified, you can overwrite the capture job's pod image.
Use ghcr.io image in default debug mode:
kubectl retina capture create \
  --name capture-test \
  --host-path test \
  --namespace capture \
  --node-selectors "kubernetes.io/os=linux" \
  --debug
Use custom retina-agent image by specifying it in the RETINA_AGENT_IMAGE environment variable:
RETINA_AGENT_IMAGE=<YOUR RETINA AGENT IMAGE> \
kubectl retina capture create \
  --name capture-test \
  --host-path test \
  --namespace capture \
  --node-selectors "kubernetes.io/os=linux" \
  --debug
Cleanup
By default (--no-wait=true), the CLI exits right after creating the capture jobs and leaves them in the cluster. Delete them with kubectl retina capture delete --name <capture-name>, where <capture-name> is the value of --name (retina-capture by default).
When --no-wait=false is specified, the CLI waits for the jobs to complete, then deletes the jobs and the secrets it created. If the jobs do not complete in time, they are kept for debugging and must be deleted manually.
Automatic Cleanup After Upload
When using --cleanup-after-upload with a remote storage destination (--blob-upload, --s3-bucket, or --pvc), Retina will automatically delete the capture files from the node's host path after the data has been successfully uploaded to remote storage.
This flag works with both --no-wait=true (default) and --no-wait=false:
--no-wait=true(default): The CLI exits immediately. Jobs are assigned a TTL (5 minutes after completion) so Kubernetes automatically garbage-collects them along with their secrets.--no-wait=false: The CLI waits for all jobs to complete, then deletes the jobs and secrets itself.
In both modes, the capture agent removes the host-path files once the upload succeeds.
kubectl retina capture create --name my-capture --node-names "node1" \
  --blob-upload "<Blob SAS URL>" \
  --cleanup-after-upload
If any capture job fails, the host-path files are preserved for debugging.